Sunday, August 5, 2012

Big (unstructure) Data, Grid computing, Hadoop, HDFS & BigTable


Big Data => It is really very big data, imaging u have perabyte data to be processed

You have app server and db. If ur app server need to process perabyte data, it needs to retrieve and copy the data from db to app server first, then process. This is traditional computing, move the data close to processing logic.

if it is small data, it is ok and right way to do that. But if the data volume is big, moving data from db to app server could take days. Just imaging how long it take to copy perabyte data files from one server to another server.

In this case, grid computing comes in and move the logic close to data rather than moving data to processing logic.

If we move logic to data, first of all, you save the time of moving data around. Then, people may argue, then u need to move result back, sure, but most of time, we need to process more data to produce one result, otherwise there is no point to process it, but copy it only.

Doing work by one man is less productive than doing work by more man. The best stratigy is allocate some time to teach others to do the same work and then get others to teach others recursively and do the work. The effect will be 2*2*2*..... faster than doing it alone.

So, we divide & distribute the data to different machines, teach & monitor (Hadoop and map & reduce model - It enables applications to work with thousands of computational independent computers and petabytes of data) them process currently, this is where distributed file system comes into picture (HDFS).

Instead of distributed file system, it could be nicer if we can put them into dictributed db as it could be easier to manage them.

So, What DB we can use? Big Data means unstructured data and it could include text strings, documents of all types, audio and video files, metadata, web pages, email messages, social media feeds, form data, and so on.  Big Data may well have different data types within the same set that do not contain the same structure. The consistent trait of these varied data types is that the data schema isn’t known or defined when the data is captured and stored. Rather, a data model is often applied at the time the data is used.

Then BigTable (casandra / HBase / MongoDB) come into picture, it is more of name-value pair + timestamp (NOSQL) DB, each value may have different fields like json string and it can be a nested name-value pair and flexiable enough to cater for any data format.

{
    "_id": ObjectId("4efa8d2b7d284dad101e4bc9"),
    "Last Name": "DUMONT",
    "First Name": "Jean",
    "Date of Birth": "01-22-1963"
},
{
    "_id": ObjectId("4efa8d2b7d284dad101e4bc7"),
    "Last Name": "PELLERIN",
    "First Name": "Franck",
    "Date of Birth": "09-19-1983",
    "Address": "1 chemin des Loges",
    "City": "VERSAILLES"
}

Fortunately, Google's BigTable Paper clearly explains what BigTable actually is. Here is the first sentence of the "Data Model" section:

A Bigtable is a sparse, distributed, persistent multidimensional sorted map. It explains that:

The map is indexed by a row key, column key, and a timestamp; each value in the map is an uninterpreted array of bytes.

HBase

HBase is a type of "NoSQL" database. "NoSQL" is a general term meaning that the database isn't an RDBMS which supports SQL as its primary access language, but there are many types of NoSQL databases: BerkeleyDB is an example of a local NoSQL database, whereas HBase is very much a distributed database. Technically speaking, HBase is really more a "Data Store" than "Data Base" because it lacks many of the features you find in an RDBMS, such as typed columns, secondary indexes, triggers, and advanced query languages, etc.

When Should Use HBase?

HBase isn't suitable for every problem.

First, make sure you have enough data. If you have hundreds of millions or billions of rows, then HBase is a good candidate. If you only have a few thousand/million rows, then using a traditional RDBMS might be a better choice due to the fact that all of your data might wind up on a single node (or two) and the rest of the cluster may be sitting idle.

Second, make sure you can live without all the extra features that an RDBMS provides (e.g., typed columns, secondary indexes, transactions, advanced query languages, etc.) An application built against an RDBMS cannot be "ported" to HBase by simply changing a JDBC driver, for example. Consider moving from an RDBMS to HBase as a complete redesign as opposed to a port.

Third, make sure you have enough hardware. Even HDFS doesn't do well with anything less than 5 DataNodes (due to things such as HDFS block replication which has a default of 3), plus a NameNode.

HBase can run quite well stand-alone on a laptop - but this should be considered a development configuration only.

What Is The Difference Between HBase and Hadoop/HDFS?

HDFS is a distributed file system that is well suited for the storage of large files. It's documentation states that it is not, however, a general purpose file system, and does not provide fast individual record lookups in files. HBase, on the other hand, is built on top of HDFS and provides fast record lookups (and updates) for large tables. This can sometimes be a point of conceptual confusion. HBase internally puts your data in indexed "StoreFiles" that exist on HDFS for high-speed lookups.

What are the real life BIG DATA use cases we can use Hadoop or similar technologies and where to start?

Check out Cloudera and use cases from their recommendation:

 E-tailing

  • Recommendation engines — increase average order size by recommending complementary products based on predictive analysis for cross-selling.
  • Cross-channel analytics — sales attribution, average order value, lifetime value (e.g., how many in-store purchases resulted from a particular recommendation, advertisement or promotion).
  • Event analytics — what series of steps (golden path) led to a desired outcome (e.g., purchase, registration).

Financial Services

  • Compliance and regulatory reporting.
  • Risk analysis and management.
  • Fraud detection and security analytics.
  • CRM and customer loyalty programs.
  • Credit scoring and analysis.
  • Trade surveillance.

Government

  • Fraud detection and cybersecurity.
  • Compliance and regulatory analysis.
  • Energy consumption and carbon footprint management.

Health & Life Sciences

  • Campaign and sales program optimization.
  • Brand management.
  • Patient care quality and program analysis.
  • Supply-chain management.
  • Drug discovery and development analysis.

Retail/CPG

  • Merchandizing and market basket analysis.
  • Campaign management and customer loyalty programs.
  • Supply-chain management and analytics.
  • Event- and behavior-based targeting.
  • Market and consumer segmentations.

Telecommunications

  • Revenue assurance and price optimization.
  • Customer churn prevention.
  • Campaign management and customer loyalty.
  • Call Detail Record (CDR) analysis.
  • Network performance and optimization.

Web & Digital Media Services

  • Large-scale clickstream analytics.
  • Ad targeting, analysis, forecasting and optimization.
  • Abuse and click-fraud prevention.
  • Social graph analysis and profile segmentation.
  • Campaign management and loyalty programs.

Thursday, August 2, 2012

AppDynamics ? What, Why & How


If you ask me what is "AppDymamics", in my own words, it is real-time web application profiler and monitoring tool, reason i called it in such way is the features i used most in the free version. 


Actually, AppDynamics call itself Application Performance Management (APM) product and has more features then i blogged here. This post is just a jump-start and personal experience of AppDymamics Lite (vs Commercial version) in my development experience.


Two most important reasons made me to try it out: 

- Easy to install
My team is so busy in development and no time to setup individual application profiler on their IDEs. 

With few minutes' effort, i setup one from our DEV server and allow all my developers to use with no wait. 

- Easy to use 
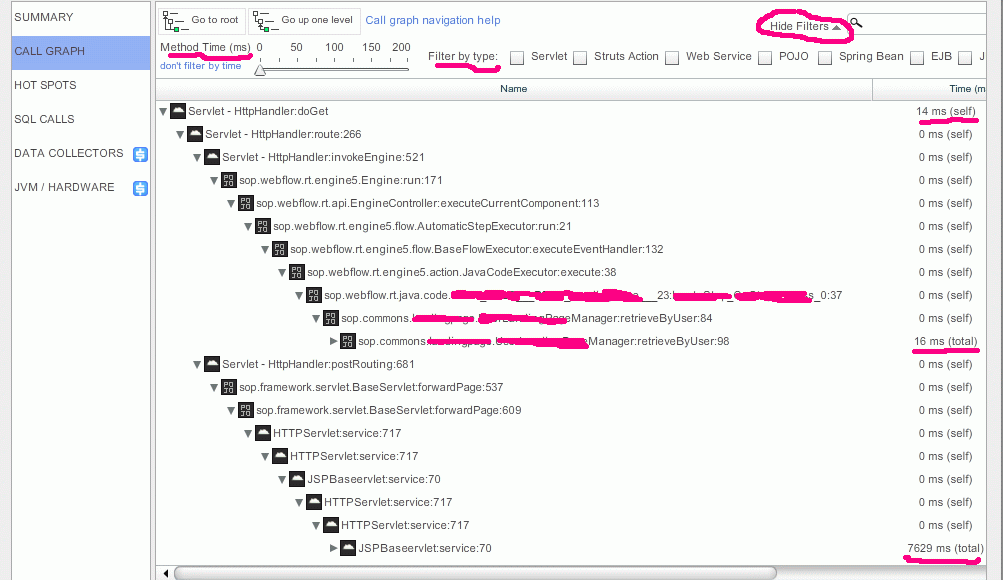
Very intuitive GUI and allow to drill down all the way to JDBC and SQL query with detail call stack (call graph) and time spending.

No training required, just follow the color code and double-click and click, click until I found the root cause in minutes.

So, When should use application Profiler instead of AppDynamics? Here is a short answer:    


WHEN TO USE A PROFILERWHEN TO USE APPDYNAMICS LITE
You need to troubleshoot high CPU usage and high memory usageYou need to troubleshoot slow response times, slow SQL, high error rates, and stalls
Your environment is Development or QAYour environment is Production or performance load-test
15-20% overhead is okayYou can't afford more than 2% overhead


Now, let me walk you through how to start & use the AppDynamics


- Download the appdynamics and install it in 4 steps


- Open web browser and browse through the slow web pages or the processes you intend to monitor and profile


- Open web browser and login AppDynamics (Be patient, if you don't see any data. AppDynamics need a short while to build and load up the analytic info) 


^Landing page will show list of recent transactions (web request) and highlight the response time in different color code depending on the settings (slow, very slow and stalling) which you can change at your own will. 


- Double-click the page name (URL) in red color and until you see the full call graph & timing of each spending.


    * First, it will drill down to all sampling of the same transaction (web request) 
   * Chose one of them and double-click to drill down to call graph
    ^you can filter the graph by method timing spending and class type (servlet, pojo, spring bean, ejb and etc)  
    
   *Click and click ... until you see something you are familiar 
    ^Take note of color code, don't confuse the total time spending (ORANGE) with method self time spending (BLUE)

As recent transactions are not good enough, we need to check out long transaction in past 30 minutes or 1 hours. Never mind, go and visit SnapShot page.

   * Click on SnapShot Tab
   ^ Too much info in the page, never mind, enable filter to view less and more concerned transactions.

    * Double-click the long transaction to pull out the call graph
   ^ There is JDBC call in this transaction

    * Right click on slow method to further expend the graph

   * Click on JDBC to check out list of executed SQL & time spending 

    * Scroll Up & Down and check what are the SQL and how much they spend in the total timing. 
    
   * Save the call graph for offline or offsite study by other developers  

    * Save to local disc and sent it to developers for further study. 
    ^ This file also includes list of executed SQL and timing of each.   

That is all, it is sweet & easy experience. In fact, i have put it up behind an Apach Server so that our offsite team can access and check out root cause of long transaction. 

Sunday, July 22, 2012

Java Heap, Stack Size, Perm Gen and Full GC tunning


A good start to understand JVM, Heap, Perm Gen and GC collector


GC Collector:


Serial Collector (-XX:+UseSerialGC)
• Throughput Collectors
> Parallel Scavanging Collector for Young Gen
 -XX:+UseParallelGC
> Parallel Compacting Collector for Old Gen
 -XX:+UseParallelOldGC (on by default with ParallelGC in JDK 6)
• Concurrent Collector
> Concurrent Mark-Sweep (CMS) Collector
 -XX:+UseConcMarkSweepGC
> Concurrent (Old Gen) and Parallel (Young Gen) Collectors
 -XX:+UseConcMarkSweepGC -XX:+UseParNewGC
• The new G1 Collector as of Java SE 6 Update 14 (-XX:+UseG1GC)

Sample JVM Parameters:


Performance Goals and Exhibits
A) High Throughput (e.g. batch jobs, long transactions)
B) Low Pause and High Throughput (e.g. portal app)
• JDK 6
A) -server -Xms2048m -Xmx2048m -Xmn1024m -XX:+AggressiveOpts
-XX:+UseParallelGC -XX:ParallelGCThreads=16
B) -server -Xms2048m -Xmx2048m -Xmn1024m -XX:+AggressiveOpts
-XX:+UseConcMarkSweepGC -XX:+UseParNewGC -XX:ParallelGCThreads=16
• JDK 5
A) -server -Xms2048m -Xmx2048m -Xmn1024m -XX:+AggressiveOpts
-XX:+UseParallelGC -XX:ParallelGCThreads=16 -XX:+UseParallelOldGC
-XX:+UseBiasedLocking
B) -server -Xms2048m -Xmx2048m -Xmn1024m -XX:+AggressiveOpts
-XX:+UseConcMarkSweepGC -XX:+UseParNewGC -XX:ParallelGCThreads=16
-XX:+UseBiasedLocking


Rule of Thumb on Best selection of

> Garbage Collector (Make sure to override GCThreads)
> Heap Size (-Xms == 1/64 Max Memory or Max Heap and
-Xmx == ¼ Max Memory or Max Heap)
> Runtime Compiler (-server vs -client)
• Desired Goals (This is a hint, not a guarantee)
> Maximum Pause Time (-XX:MaxGCPauseMillis=)
> Application Throughput (-XX:GCTimeRatio= where
Application time = 1 / (1 + n))

Do check out 1.5 paper as it comes with sample parameters for high thoughput and low latency application


If you are using 1.6, check out the difference and improvement from 1.6 paper, take note that 1.5 parameters still apply to 1.6.


A very practical and easy to understandable slide which walking you through the Sun HotSpot GC tuning tip and take-away parameters.


Wondering whether java thread stack space (Xss) and  perm gen (MaxPermSize) part of heap space. The answer is NO. That is why when u saw actually linux memory consumption is bigger than your "-Xmx" settings.

One working jvm parameters with JBoss server:

JAVA_OPTS="-server -Xms3072m -Xmx3072m -Xmn2048m -XX:MaxPermSize=256m -Dorg.jboss.resolver.warning=true -Dsun.rmi.dgc.client.gcInterval=3600000 -Dsun.rmi.dgc.server.gcInterval=3600000 -XX:ParallelGCThreads=8 -XX:+UseConcMarkSweepGC -XX:+UseParNewGC -XX:SurvivorRatio=8 -XX:TargetSurvivorRatio=90 -XX:MaxTenuringThreshold=31 -XX:+AggressiveOpts -XX:+PrintHeapAtGC -XX:+PrintGCTimeStamps -XX:+PrintGCDetails -XX:+PrintGCApplicationStoppedTime -Xloggc:/opt/jbos/server/default/log/jvmgc.log"


You have short-term memory on Linux Shell? Never mind, just check out this article and refresh your mind. 

Wednesday, July 4, 2012

Load Testing


Peak Hourly Visits and Average Visit Length

Peak Hourly Pages, Testcase Size and Duration

How Many Rows of Data Do I Need?


Recommend Readings

Oracle Archive Logging

[Original PostBasically, any change that happens in the database is first captured in a memory structure called the Log Buffer. This memory structure exists inside the Oracle Instance. The Log Buffer normally has a small footprint (somewhere in the neighborhood of 1MB). Information in the Log Buffer memory is flushed to the Redo Logs by the background process LGWR under these curcumstances:
a) every 3 seconds
b) on a commit
c) when the Log Buffer becomes 1/3 full
d) on a checkpoint

Anytime a) b) c) or d) occurs in the database, the information from the Log Buffer is written to the current Red Log by LGWR. Redo Logs are actual physical files residing on the OS. When a Redo Log becomes full, a Log File Switch occurs and a pointer is set to start writing Log Buffer information to the next Redo Log in line. You can run your database with only 2 Redo Logs, but Oracle (and common sense) recommends at least 3. 
So, after this Log File Switch, you have a Redo Log that is full and a pointer to the next Relo Log. The Redo Log that is full needs to be archived (saved somewhere else). So now, a background process called ARCH will get a nudge from LGWR saying "hey, got a redo log that needs to be archived" and ARCH will pick it up and convert it to an Archived Log file and save it in the location specified by your init.ora parameter setting called log_archive_dest_1 (or in yor flash_recovery_area, depending).
So now that the previous Redo Log has been archived, it can be overwritten by LGWR when necessary (e.g., Redo Logs are written to in a round-robin fashion and when Redo Log #3 fills up, the pointer goes back around to Redo Log #1. So if you're in archivelog mode and redo log #1 hasn't been completely archived by ARCH yet, and LGWR needs to write to Redo Log #1, then your database "hangs" until that Redo Log #1 is freed up to be written to again).

So, what is the advantage of having Archived Logs? Say for example you expereince severe corruption or a database crash that required you to restore some datafiles from 7 hours ago. If you have all the archived logs from that pint in time (7 hours ago) up until the oment of the crash, you can apply (or "roll forward") all the changes contained in those archived logs against the restored datafiles. Basically this replays all the changes in the database over the past 7 hours. After recovering the last archived log, Oracle will then look to roll forward even more by using the online redo logs. If those online redo logs contain changes necessary, Oracle will apply those changes also. Basically, you can recover from a serious error all the way up to just before the error occurred. Minimal data loss is the advantage here. you can't do this when you're not in archivelog mode, because all the changes over the past 7 hours are lost because the redo logs just keep overwriting themselves and all the changes are lost between the time of your last backup and the time of the crash.
As the mantra goes . . . if you don't care if your database loses data, then run in noarchivelog mode. If you care about your data and don't want to lose it, then run the database in archivelog mode.

Memory, Swap, Process, Thread, File, Data Storage and Tunning


Physical and virtual memory

Traditionally, one has physical memory, that is, memory that is actually present in the machine, and virtual memory, that is, address space. Usually the virtual memory is much larger than the physical memory, and some hardware or software mechanism makes sure that a program can transparently use this much larger virtual space while in fact only the physical memory is available.

Nowadays things are reversed: on a Pentium II one can have 64 GB physical memory, while addresses have 32 bits, so that the virtual memory has a size of 4 GB. We'll have to wait for a 64-bit architecture to get large amounts of virtual memory again. The present situation on a Pentium with more than 4 GB is that using the PAE (Physical Address Extension) it is possible to place the addressable 4 GB anywhere in the available memory, but it is impossible to have access to more than 4 GB at once.


Swap Space


Linux divides its physical RAM (random access memory) into chucks of memory called pages. Swapping is the process whereby a page of memory is copied to the preconfigured space on the hard disk, called swap space, to free up that page of memory. The combined sizes of the physical memory and the swap space is the amount of virtual memory available.


Linux has two forms of swap space: the swap partition and the swap file. The swap partition is an independent section of the hard disk used solely for swapping; no other files can reside there. The swap file is a special file in the filesystem that resides amongst your system and data files


How big should my swap space be?


Linux and other Unix-like operating systems use the term "swap" to describe both the act of moving memory pages between RAM and disk, and the region of a disk the pages are stored on. It is common to use a whole partition of a hard disk for swapping. However, with the 2.6 Linux kernel, swap files are just as fast as swap partitions. Now, many admins (both Windows and Linux/UNIX) follow an old rule of thumb that your swap partition should be twice the size of your main system RAM. Let us say I've 32GB RAM, should I set swap space to 64 GB? Is 64 GB of swap space really required? How big should your Linux / UNIX swap space be?


taskset  -p 
i.e.
taskset 1 -p 12345
to set process 12345 to use only processor/core 1
The bitmask can be a list (i.e. 1,3,4 to use cores 1 3 and 4 of a 4+ core system) or a bitmask in hex (0x0000000D the 1,3,4, 0x00000001 for just core 1)
taskset is usually in a package called shedutils.
Edit: almost forgot... If you want to set the affinity of a new command instead of change it for an existing process, use:
taskset   []...[]


Maximum number of threads per process in Linux

number of threads = total virtual memory / (stack size*1024*1024)

Java Process & Thread Limit on Linux

Maximum threads managed by java


Heap size                                                                                            

Java Heap size does not determine the amount of memory your process uses

If you monitor your java process with an OS tool like top or taskmanager, you may see the amount of memory you use exceed the amount you have specified for -Xmx. -Xmx limits the java heap size, java will allocate memory for other things, including a stack for each thread. It is not unusual for the total memory consumption of the VM to exceed the value of -Xmx.


Garbage collection


There are essentially two GC threads running. One is a very lightweight thread which does "little" collections primarily on the Eden (a.k.a. Young) generation of the heap. The other is the Full GC thread which traverses the entire heap when there is not enough memory left to allocate space for objects which get promoted from the Eden to the older generation(s).

If there is a memory leak or inadequate heap allocated, eventually the older generation will start to run out of room causing the Full GC thread to run (nearly) continuously.

The amount allocated for the Eden generation is the value specified with -Xmn. The amount allocated for the older generation is the value of -Xmx minus the -Xmn. Generally, you don't want the Eden to be too big or it will take too long for the GC to look through it for space that can be reclaimed.

Tuesday, April 17, 2012

Open Source Enterprise Service Bus & Comparison

Open Source Enterprise Service Bus in Java

Top Open Source ESB Projects

Comparison from Tijs Rademakers - Author of Open Source ESBs in Action

Mule --> Custom architecture, XML based configuration, easy for Java developers


ServiceMix 3 --> JBI based, focus on XML messages

ServiceMix 4 --> OSGi based, integrated with Camel configuration, also provides support for JBI

JBoss ESB --> Custom architecture, runs on JBoss application server, fits great with JBoss products

Synapse --> Focus on WS-*, Rest, build on Axis 2, great if you need things like WS-Security etc

OpenESB --> JBI and OSGi based, runs on Glassfish, nice tool support with Netbeans

Camel --> XML and Java DSL configuration, no container, support for EIPs and lots of transports

Spring Integration --> XML and Java annotation configuration, no container, support for EIPs

PetTALS --> JBI based, nice admin console, French based

Tuscany --> SCA based, provides support for WS-*, focus on service development not integration

THE FORRESTER ESB EVALuATIOn (Q2 2011)

The evaluation uncovered a market in which many familiar faces continue to thrive (see Figure 5):

· Software AG, Tibco, Oracle, Progress Software, and IBM are Leaders for ESB as well as CIS. These five vendors achieved Leader status in the 2009 ESB Forrester Wave evaluation and in the 2010 CIS Forrester Wave evaluation, thus garnering the top position in the integration software
provider market.

· FuseSource and WSO2 also scored as Leaders. FuseSource and WSO2 also scored highly in most of the evaluated areas; each of these vendors’ products represents a solid ESB solution that would be a good choice for meeting many enterprise integration and service-oriented architecture requirements.

· MuleSoft, IBM’s WESB, and Red Hat products scored as Strong Performers. Though MuleSoft, IBM’s WebSphere ESB (WESB), and Red Hat products were missing some features, they still made the Strong Performer category. These products lack the same level of ESB support as the Leaders, but in most cases the differences were small. Consequently, each of these products may also be a very good fit in many enterprises, depending on the specifics of the situation.

This evaluation of the enterprise service bus market is intended to be a starting point only. We
encourage readers to view detailed product evaluations and adapt the criteria weightings to fit their individual needs through the Forrester Wave Excel-based vendor comparison tool.

ESB Comparision from OpenLogic

Wednesday, June 8, 2011

Oracle Universal Content Management (UCM) aka Stellent

Original post from here

Oracle Universal Content management or UCM is what was erstwhile Stellent Content Server. It is an enterprise wide content management, revisioning and controlling system.

In layman's terms the idea is to organize the documents of your company on a central server maintaining informations (metadata) about the documents and tracking the progress of the documents through revisioning and version control. Users would be able to upload (check in) documents based on their permission levels (through security groups and accounts) and before the document is released for everyone to view and download (check out), an approval heirarchy (workflow) can be set.

This simple concept brings in an amazing level of order in the chaos that can be in an enterprise's document management requirements.

Other than simply checking in and checking out documents, the list of functionalities that come with UCM are manyfold. Your companies website can be hosted through UCM where users simply check in their contribution as word documents and instantly the content appears on the website in a predefined template. Project documents of your company are handled by Collaboration Projects component of UCM where "on the fly" access and document management can be handled.

This brings me to the important part of components in UCM (stellent). UCM is an extensible content management system which means that through installing custom components, functionalities can be added or modified. Notable components are folders, dynamic convertor, pdf convertor, threaded discussions, collaboration projects, extranetLook, folios etc and many others.

Architecture of Stellent or Universal Content Management


The Main players in the working of UCM are

Web Browser

A user interacts with the content server through a web browser. Even though through the Desktop Integration Component (DIS) windows explorer can be used as an interface, however the simple web browser is the default interface.

Web Server

Obviously, a web server will be handling the request sent by the web browser to the content server. Microsoft IIS, Apache, Oracle iAS can all be used as a web server of choice. Installing with IIS is actually the easiest.

Content Server

Content Server is the core service which provides all the functionalities. At it's core Content Server consists of Java Applications that require a Java Runtime environment installed on your server.

Vault and Web Layout

When users check-in content, they are stored in a folder on the server called vault in their "native format". However, if you have installed the dynamic convertor a web layout directory stores the html conversions of your native files.

Search Index and Search Engine

Searching is the most useful and the most necessary feature of the content server. Users can search for content by querying on the metadata or use a Full Text Searching provided you have dynamic convertor installed.

Oracle Database

Oracle UCM runs on DB2, Microsoft SQL server in addition to Oracle. When installing UCM you will need to create a user for Content Server to use to connect to the database.

So these were the principal components of Oracle UCM. An image is attached which shows gives a graphical representation of the architecture.

To get to know more, read following documents on Club-Oracle

•Oracle UCM or stellent Beginner's Documents and tutorials
•Installing Stellent or Oracle Universal Content Management
•Steps to install Site Studio and other components
•How to create a Dependent Choice list in Oracle UCM (Stellent)

Wednesday, May 25, 2011

Hyperion Reporting and Analysis Architecture

Various components of Hyperion (source):


Workspace is a common window to view the contents of all Hyperion components.
Hyperion Reporting and Analysis:

One zero-footprint Web-based thin client provides users with access to content:
● Financial reporting for scheduled or on-demand highly formatted financial and operational reporting from most data sources including Hyperion Planning – System 9 and Hyperion Financial Management – System 9
● Interactive reporting for ad hoc relational queries, self-service reporting and dashboards against ODBC data sources
● SQR Production reporting for high volume enterprise-wide production reporting.
● Web analysis for interactive ad hoc analysis, presentation, and reporting of multidimensional data.

Hyperion Reporting and Analysis Architecture


Client: The client tools consist of

Workspace: It is a DHTML Zero footprint web client and provide the user interface for viewing and interacting with the reports created using Authoring studios.
Authoring Studios: These are the client interfaces to create the reports and includes-

(a) Hyperion Interactive Reporting Studio: Windows client where you can connect to different data sources including the flat files and build very interactive presentation reports like reports in simple tabular format, pivot reports, graphs and charts with drill anywhere feature which means that you don’t have to define the hierarchy or drill path and slicing and dicing and Dashboards with many features like hyperlinks to the details reports and embedded browser which can be used to view any other web application to open within the Dashboards.

(b) Hyperion Financial Reporting Studio: Windows client where you can connect to the multidimentional data sources and create highly formatted financial reports by simply dragging and dropping rows and columns and defining page breaks.

(c) Hyperion SQR Reporting Studio: Windows client where you can connect to wide range of data sources and produce high volume pixel perfect operational reports and can be scheduled.

(d) Hyperion Web Analysis: Java applet where you can connect to different data sources using JDBC and build interactive reports and dashboards.
Smart view for office: This is a tight integration with Microsoft Office tools where ou can do analysis like drill downs, keep only and remove only options, POV manager, data refresh, copying data cells and pasting to MS Word and Powerpoint which automatically gets refreshed if the data changes in the source etc. There is one more component in smart wiew which is Hyperion Visual Explorer(HVE), where again you can view the data in presentable interactive graphs and charts.

Application Layer: It consists of two parts :

1. Web Tier: It consists of two parts (a) Web server- to send and receives content from the web clients. (b) Application server- it is a J2EE application server.
Web server and application server are connected using an HTTP connector.
The web Tier hosts the web applications like workspace, web analysis, interactive , SQR and financial reporting applications.

2. Services Tier: It contains services and servers that controls the functionality of the web applications and clients. Core services handles repository information, authorization, session information, documents publication.

More to read:

http://www.youtube.com/watch?v=j5REDY8cpiM&NR=1
http://download.oracle.com/docs/cd/E12032_01/doc/nav/portal_1.htm
http://businessintelligence.ittoolbox.com/groups/technical-functional/hyperion-admin-l/ir-92-hyperion-biservice-is-not-accessible-1543368
http://businessintelligence.ittoolbox.com/groups/technical-functional/brio-l/hyperion-system-93-adding-additional-bi-service-memory-exhausted-4039255
http://businessintelligence.ittoolbox.com/groups/technical-functional/brio-l/active-x-client-hyperion-931-out-of-memory-on-db2-2288146
http://businessintelligence.ittoolbox.com/groups/technical-functional/brio-l/hyperion-out-of-memory-error-2099199
http://businessintelligence.ittoolbox.com/groups/technical-functional/hyperion-bi-l/hyperion-designer-85-out-of-memory-for-large-queries-1332854
http://essbase.ru/archives/wiki/obiee-11gr1-architecture-and-use-of-weblogic-server
https://www.packtpub.com/toc/business-analysts-guide-oracle-hyperion-interactive-reporting-11-table-contents

Monday, May 23, 2011

Understanding JSON: the 3 minute lesson

Source

What does it stand for?
JavaScript Object Notation.

And what does that mean?
JSON is a syntax for passing around objects that contain name/value pairs, arrays and other objects.

Here's a tiny scrap of JSON:

{"skillz": {
"web":[
{"name": "html",
"years": "5"
},
{"name": "css",
"years": "3"
}],
"database":[
{"name": "sql",
"years": "7"
}]
}}

You got that? So you'd recognise some JSON if you saw it now? Basically:

Squiggles, Squares, Colons and Commas
Squiggly brackets act as 'containers'
Square brackets holds arrays
Names and values are separated by a colon.
Array elements are separated by commas

JSON is like XML because:
They are both 'self-describing' meaning that values are named, and thus 'human readable'
Both are hierarchical. (i.e. You can have values within values.)
Both can be parsed and used by lots of programming languages
Both can be passed around using AJAX (i.e. httpWebRequest)

JSON is UNlike XML because:
XML uses angle brackets, with a tag name at the start and end of an element: JSON uses squiggly brackets with the name only at the beginning of the element.
JSON is less verbose so it's definitely quicker for humans to write, and probably quicker for us to read.
JSON can be parsed trivially using the eval() procedure in JavaScript
JSON includes arrays {where each element doesn't have a name of its own}
In XML you can use any name you want for an element, in JSON you can't use reserved words from javascript
But Why? What's good about it?
When you're writing ajax stuff, if you use JSON, then you avoid hand-writing xml. This is quicker.

Again, when you're writing ajax stuff, which looks easier? the XML approach or the JSON approach:

The XML approach:
bring back an XML document
loop through it, extracting values from it
do something with those values, etc,
versus
The JSON approach:
bring back a JSON string.
'eval' the JSON
So this is Object-Oriented huh?
Nah, not strictly.

JSON provides a nice encapsulation technique, that you can use for separating values and functions out, but it doesn't provide anything inheritence, polymorphism, interfaces, or OO goodness like that.

And it's just for the client-side right?
Yes and no. On the server-side you can easily serialize/deserialize your objects to/from JSON. For .net programmers you can use libraries like Json.net to do this automatically for you (using reflection i assume), or you can generate your own custom code to perform it even faster on a case by case basis.

´